The AI Scientist Shows Why Autonomous Research Still Falls Short
AI KAPTAN
August 20, 2026
Quick answer: The AI Scientist can generate research ideas, write code, run experiments and produce research papers, but current evidence does not show that autonomous AI can replace human researchers in open-ended scientific work. A recent Nature report points to major limits around evaluation, research direction and full automation.
Key Facts
- Nature reported that a study posted on arXiv in late July concluded that computers are not yet ready to replace their human creators in open-ended research.
- Sayash Kapoor, a computer scientist at Princeton University and co-author of the preprint cited by Nature, said that full automation of open-ended research is not currently on the horizon.
- A team largely from Sakana AI in Tokyo introduced The AI Scientist in 2024 as a system intended to automate parts of the scientific process, from idea generation to writing and self-evaluation.
- A LinkedIn post discussing The AI Scientist stated that the system can generate ideas, write code, run experiments, plot data, write a manuscript and peer-review its own work; one paper passed the first round of review at a workshop with a 70% acceptance rate.
- An August 2026 arXiv paper on AI Research Preference Models reported that two research-selection approaches raised an average normalized score on AIRS-Bench from 0.684 to 0.711 and 0.729.
What The AI Scientist actually does
The AI Scientist is one of the clearest attempts to turn scientific research into an automated loop. According to Nature, the system was pioneered by a team mostly from Sakana AI and introduced in 2024 to automate stages ranging from generating ideas to writing and self-evaluating a paper.
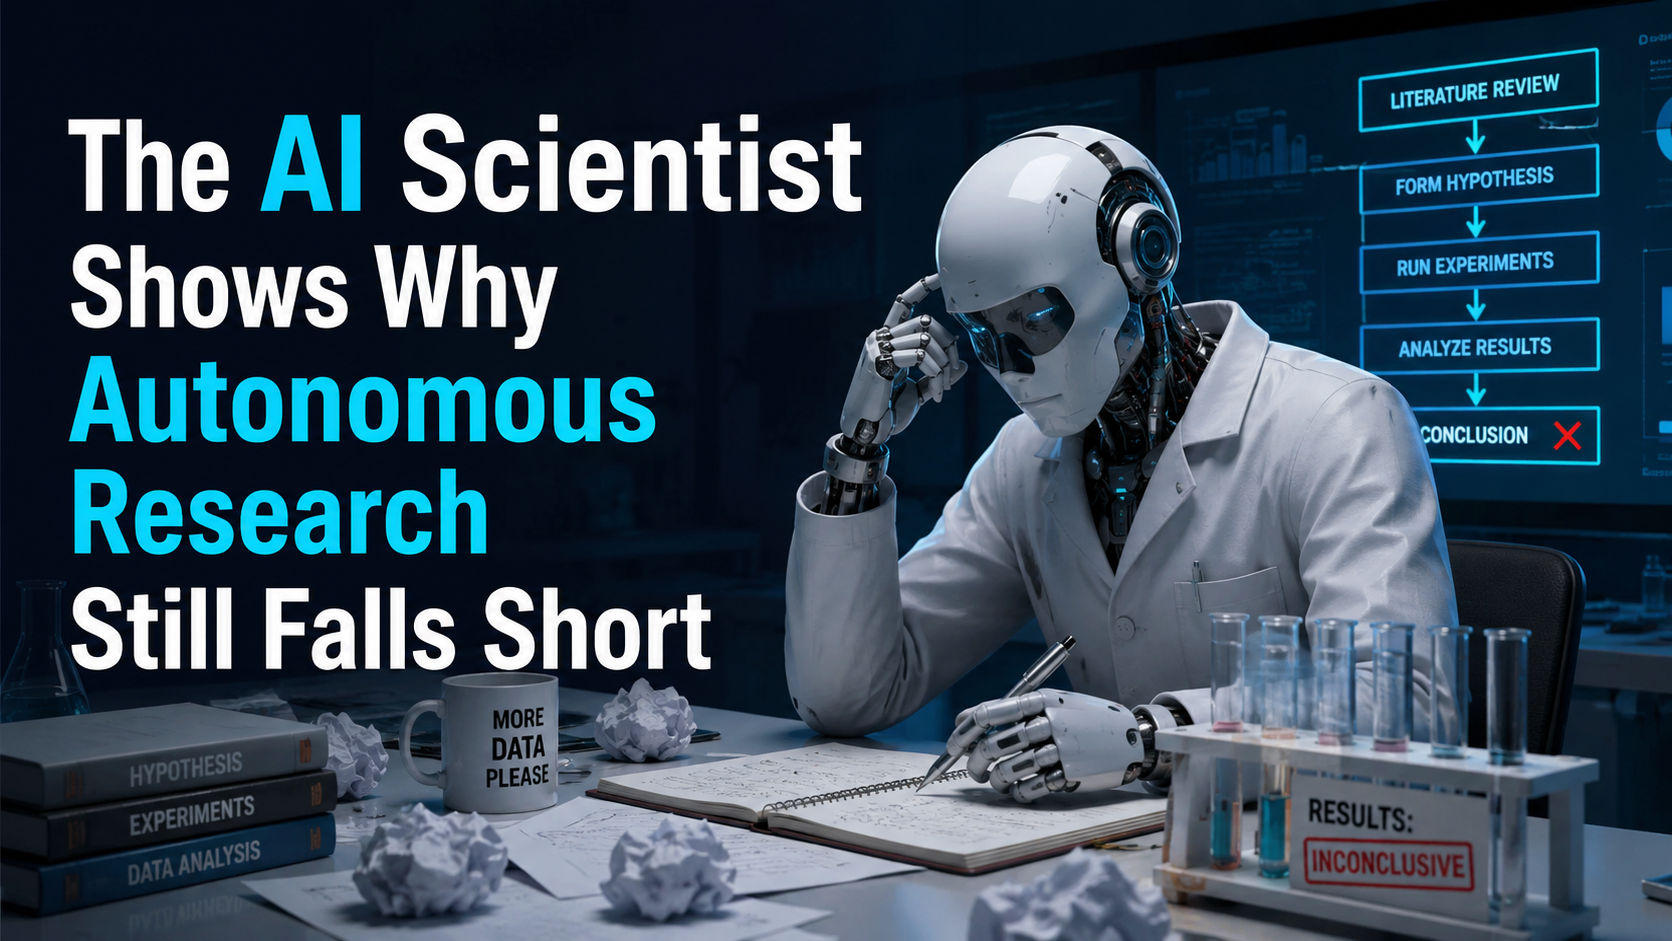
The workflow described in the research brief is unusually broad. The AI Scientist can generate research ideas, write experimental code, run experiments, produce plots, draft a manuscript and review its own output. That makes The AI Scientist more than a writing assistant or coding agent. The intended goal is to connect several research tasks into a single system.
This approach has a practical advantage in machine-learning and computer-science research. As the LinkedIn analysis in the brief notes, experiments in these fields can often be expressed as executable scripts. An agent can modify code, run the program and inspect the resulting output without waiting for a physical laboratory procedure to be completed.
That environment makes automation easier to test. It does not mean every research decision becomes easy to automate.
Why Nature says autonomous research is not ready yet
Nature's recent report, "AI isn't ready to research itself," draws a line between automating parts of research and automating open-ended scientific discovery.
According to Nature, AI systems have already made progress in AI research itself by finding ways to improve existing algorithms and by writing new ones. But Sayash Kapoor said full automation of open-ended research remains out of reach for now.
The distinction matters because open-ended research involves more than producing many candidate ideas. A system also has to decide which questions are worth pursuing, determine whether experimental results are meaningful, recognize flawed assumptions and change direction when a promising path turns out to be unproductive.
The AI Scientist can automate a sequence of tasks, but a sequence is not the same as independent scientific judgment. A system may be able to execute an experiment correctly while still pursuing an unhelpful question or drawing too much confidence from a weak result.
Nature's account of current AI research points to that gap. Progress in automating individual stages does not yet establish that an AI system can manage the full, open-ended process without human direction.
The evaluation problem is becoming a bottleneck
A separate August 2026 arXiv paper, AI Research Preference Models, describes a concrete problem facing AI research agents: proposing candidate solutions is much cheaper than evaluating them.
The paper states that an AI research agent can write a candidate solution in minutes, while evaluating that solution can require hours or days of GPU time. That creates a budget-allocation problem. If an agent can generate more experiments than it can afford to run, choosing the right experiments becomes part of the research process itself.
The researchers introduced AI Research Preference Models, or RPMs, to predict which candidate solutions are most worth executing before paying the full cost of running them. The paper describes two approaches: an inference-only model that reasons over plans, code and previous solutions, and an agentic model that also performs small-scale pilot experiments before making a decision.
Integrated into the AIRA-dojo search agent, the approaches increased the average normalized AIRS-Bench score from 0.684 to 0.711 and 0.729, according to the paper.
For The AI Scientist and similar systems, this highlights a basic constraint: generating experiments at scale is not enough. Autonomous research also depends on selecting which experiments deserve limited computing resources.
Passing review is not the same as proving autonomy
The research brief also includes a claim that a paper generated by The AI Scientist passed the first round of review at a workshop associated with a top-tier machine-learning conference.
The same LinkedIn post notes an important qualification: the workshop had a 70% acceptance rate. That context limits what the result can establish about the quality of autonomous scientific research.
A paper clearing an initial review stage can demonstrate that an AI-generated submission met a particular threshold in a particular setting. It does not demonstrate that The AI Scientist can independently identify important research problems, conduct reliable research across fields or replace human researchers.
That distinction is consistent with Nature's broader conclusion. The available evidence supports the idea that AI can perform increasingly large portions of research workflows. It does not yet support full automation of open-ended research.
Where The AI Scientist fits today
The most defensible way to view The AI Scientist is as an experiment in research automation rather than a finished replacement for scientific researchers.
The system demonstrates how far an automated workflow can extend when the research environment is software-based. Ideas, code, experiments, figures and manuscripts can all be represented digitally, allowing an AI system to move through multiple stages without a human manually operating each tool.
But the same digital environment exposes another issue: an autonomous system can generate possibilities faster than it can validate them. The AI Research Preference Models paper shows that experiment selection alone can become a limiting factor when execution costs rise.
The current question is not simply whether an AI system can produce a research paper. The more difficult question is whether an AI system can repeatedly choose worthwhile questions, allocate resources intelligently and assess its own results with enough reliability to operate without sustained human judgment.
Based on the research in this brief, The AI Scientist has not reached that point. It has shown that more of the research loop can be automated, while Nature's reporting and the newer work on research-agent evaluation show why closing the loop remains difficult.
FAQ
What is The AI Scientist?
The AI Scientist is an AI research system introduced by a team largely from Sakana AI in 2024. It is designed to automate stages including idea generation, coding, experiments, paper writing and self-evaluation.
Can The AI Scientist replace human researchers?
Current evidence in the research brief says no. Nature reported that full automation of open-ended research is not currently on the horizon, even as AI systems automate more individual research tasks.
Did an AI Scientist paper pass peer review?
A paper generated by The AI Scientist passed the first round of review at a workshop, according to a LinkedIn post in the research brief. The same post noted that the workshop had a 70% acceptance rate.
Why is evaluating AI research expensive?
The August 2026 AI Research Preference Models paper says an agent can generate a candidate solution in minutes, while evaluating it can take hours or days of GPU time. This forces research agents to decide which experiments are worth running.
What are AI Research Preference Models?
AI Research Preference Models are systems designed to predict which candidate research solutions are most worth executing. The paper evaluated inference-only and agentic versions within the AIRA-dojo search agent.
What is the main limitation of autonomous AI research today?
The central limitation described in the brief is open-ended scientific judgment. Automating experiments and paper generation does not yet mean an AI system can independently select worthwhile problems, evaluate results and direct an entire research program.
Author